2026-06 Db2 vNext Migration – Are YOU ready, Player One?

This month I wish to stroll along the dangerous and difficult road called Db2 Release Migration. We all love it as it means a new release with all new go-faster features and whizzbang things to play with but we also all hate it as it means we have things to do before we can actually migrate and get to this new promised land.

With Db2 for z/OS vNext coming up soon we are now back in the Driving Seat!

The list of deprecated items is pretty long and now about 80% of them have been finally deleted. If you have, or use, any of them you will *not* be joining the rest of us on the other side of the valley where the grass is definitely much greener!

The list of killed off items is:

  • Simple tablespaces
  • Segmented tablespaces
  • Classic partitioned tablespaces (With or without Index based partitioning)
  • Basic (Six byte) format
  • BRF (Basic Row Format so not yet at RRF – Reordered Row Format)
  • Hash Access
  • Synonyms
  • VTAM/SNA

Haakon Roberts shared this data at the IDUG EMEA 2024 in Valencia and it was the first time we had all seen an inkling of what would come. The real surprise, at least for me, was the requirement to remove VTAM/SNA support and move over to TCP/IP. The rest we had all known about for years but killing off VTAM/SNA was brand new!

CATMAINT to the Rescue?

Nope! None of these features will be automagically fixed by running a CATMAINT. It is all manual work and up to us, the DBAs fighting at the front, to fix „When we have some spare time…“

An ALTER a Day keeps the Dr at Bay

The basic „cure“ for most of these problem children is simply an ALTER and a REORG, but it *never* is that easy, is it? To fix segmented or simple tablespaces with just one table within them it is an ALTER to MAXPARTITIONS 1 which will kick the tablespace into the world of UTS PBG. Follow up with a REORG with inline statistics and a REBIND of all invalidated packages and you are done.

More than one?

If you have multi-table tablespaces then you must be at Db2 12 FL508 or higher and create a new set of tablespaces that match *exactly* the current ones for BUFFERPOOL, CCSID and LOGGED attributes. Then you use the ALTER … MOVE TABLE syntax for each table. An actioning REORG followed by a full RUNSTATS on each new tablespace afterwards with SHRLEVEL REFERENCE is then required to get the RTS statistics inline. Now do a REBIND of all invalidated packages and you are done.

Time for the Classics?

If you have any really, really old index-based partitioning tables, you must do two ALTERs within one commit scope. The first flipping the Partitioning Index to NOT CLUSTER and then back to CLUSTER. Now you are at table-based partitioning so read on!

Table-based partitioning

At this point it is an ALTER to SEGSIZE 64 which will kick these babies into the fun world of UTS PBR.

For both Classic cases, follow up with a REORG with inline statistics and a REBIND of all invalidated packages and you are done.

Six Byte RBA/LRSN, anyone?

If any of your tablespaces or indexspaces have not got 10 Byte RBA/LRSN then you must REORG them to action this. One little problem here is if the space is an XML space (Type = ‚P‘) then you must first check its base table’s tablespace to see if that is a UTS space. If so then all is good, otherwise you have a non-versioning XML space which will require this four-step fix:

1. DSN1COPY to generate image copy for XML data

2. Drop XML column from base table

3. Recreate the XML column in the base table

4. LOAD REPLACE to load the XML data from the image copy generated by step 1.

Invalidated Packages?

Yup! All of these ALTERs and the actioning REORGs with their inline/afterwards RUNSTATS will happily invalidate any and all packages that refer to the objects… This is a major pain as your access paths can then very easily go south! This is time for our tool BindImpactExpert (BIX) to ride to the rescue. As long as you are running with EXPLAIN(YES) – and I sincerely hope you are!!! – BIX can be used to highlight any and all changed access paths enabling you to be proactive with corrective measures.

Definitely evil DEFINE NO

DEFINE NO objects are great as SQL can SELECT from them really fast! They take up next to no disk space and require no REORG or COPY processing as there is no VSAM dataset. The problem with these little devils is that REORG is actually *not* permitted on them! One exception to this rule is if the TS/TP was created with BRF, as then you can REORG with the option ROWFORMAT RRF and this REORG will just flip a bit or two in the catalog/directory and nothing else.

And???

That means that all the ALTERs you might have done are „hanging in the wind“. IBM state that an INSERT/LOAD will materialize the VSAM cluster(s) but who wants to do that? The only way forward is to extract the DDL that created them, DROP them and then reCREATE them all as DEFINE NO again. As when recreated they will be valid for vNext, of course then a REBIND of all invalidated packages is also required and you are done.

Devil in the Details

For BRF partitions the fixing REORG will fail if any table has a validation procedure (VALPROC table column) or edit procedure (EDPROC tabel column) defined. If this is the case then the procedures must first be dropped before the REORG and afterwards added back.

Did they make a HASH of it?

HASH access came in with a big fanfare, we finally had an access path like IMS HDAM, but it died a death very quickly and the fix here is ALTER with DROP ORGANIZATION. Naturally, this drops the hash index and so you must then create a new index for SQL use and – guess what else you must do? Of course, a REORG with inline statistics and a REBIND of all invalidated packages and you are done.

Simply SYNONYMs

I wrote a Blog about all these beasts.

Yes, over ten years ago! The actual fix for every synonym is straightforward:

SET CURRENT SQLID = 'Synonym schema' ;
DROP SYNONYM 'Synonym name' ;
  COMMIT ;
CREATE ALIAS 'Synonym schema'.'Synonym name'
       FOR   'Table creator'.'Table name' ;
  COMMIT ;

The problems here are that the statement SET CURRENT SQLID requires SYSADM Authorization, so this is not something I would farm out to the next student doing work experience!!! Plus, guess what you have to do afterwards??? A REBIND of all invalidated packages and possibly a chain of dependent invalidated objects as well and you are done.

TCP/IP is the Future!

It came as a surprise but there are indeed shops out there who are still using VTAM/SNA for inter-Db2 communication. The problem here is that when it was released in 1974, we all trusted each other! If you were connected to DB2A and just hopped over to DB2B it happily trusted you as you „were already on a DB2A so you must be good guy!“ Sadly, those halcyon days are long gone. These days we have „Zero trust“ as the norm – a real shame but it is what it is!

Reason for Change?

TCP/IP has enhanced security (AT-TLS and JSON Web Tokens), it can use 64-bit communication buffers and is zIIP eligible. You will save CPU and be much more secure, so going to this is really no question – However, this is a project all on its own – not something for a Friday afternoon at 4 o’clock!

Big Switch?

To switch off VTAM/SNA you should do several things. First clear out any and all old entries in the CDB tables LULIST, LUMODES, MODESELECT and all but the empty LUNAME entry from LUNAMES. Then you should do a BSDS update with DSNJU003 setting the IPNAME for that subsystem to be the real host name. Just doing that switches off VTAM/SNA for that member. If doing all this then also go to SECPORT usage at the same time as then your Db2s are truly secure! Your auditors will love you.

IBM Details

Are here.

Let’s get it sorted!

Yes, even all the sort workspaces must be cleaned-up and moved to PBG spaces. You really need a lot of 32k, a few 4k, and you need to know exactly how many FOR SORT and how many FOR DGTT (The new syntax in Db2 13 FL508) you require and need. No more guessing at which workload is going into which work tablespace.

  • FOR SORT specifies that the table space is used for processing other than declared global temporary table (DGTT) work, such as sort, joins, created global temporary tables, query parallelism, trigger transition tables, and so forth.
  • FOR DGTT specifies that the table space is used for DGTT work and processes that use internal temporary tables, such as scrollable cursors and INSTEAD OF triggers.

Remember that here no ALTER helps – you must DROP and CREATE the work spaces again… But hey! At least no REORG, RUNSTATS and REBINDs are required!

<PHEW> That’s a Ton of Stuff to do…

Wouldn’t it be cool if there was a nice small bit of freeware out there that listed out all the stuff you have to do to actually get ready for Db2 vNext! In fact, you cannot even get to Db2 13 FL511 as that will stop you with any of the above-mentioned items!

What Luck – SEG to the Rescue!

Yes indeed, we have a bit of freeware called MigrationReadiness HealthCheck for Db2 z/OS (MRHC) that runs through your Db2 subsystems and shows you all the KPIs you have as well as highlighting all the Migration Blockers, as I call them. There is also a pay-ware version that then actually creates all of the ALTERs, REORGS, RUNSTATS and REBINDs for you as well.

How does it look?

It looks cool, of course! Here are a few example screen grabs of how it looks in my little Db2 13 data-sharing test system and what it offers:

Db2 MigrationReadiness HealthCheck V2.1 for SD1 V13R1M509
               started at 2026-05-28-11.08.24
            Lines with *** are deprecated features                              
            Lines with MMM are migration blockers                               
            Lines with XXX are definition errors                                 
Number of DATABASES          :  225                                              
  # of empty DATABASES       :   48                                             
  # of implicit DATABASES    :  110                                              
  # of empty implicit DBs    :   46
                                              
Number of TABLESPACES        : 4995                                              
  of which HASH organized    :    0                                              
  of which PARTITION CLASSIC :    0                                              
    # Partitions             :    0                                              
  of which SEGMENTED         :   27 MMM                                          
  of which SIMPLE            :    3 MMM                                          
  of which LOB               :   99                                              
  of which UTS PBG           : 4833 
    # Partitions             : 4834                                              
  of which UTS PBR (Absolute):    1                                              
    # Partitions             :    6     
  of which UTS PBR (Relative):   10                                              
    # Partitions             : 2215                                              
  of which XML               :   22 
             
Number of TSs as LARGE       :    0                                              
Number of empty tablespaces  :    7                                              
Number of multi-table TSs    :   12 MMM                                          
  # of tables within these   :   49       
.
.
Number of table partitions   : 7211   
  of which DEFINE NO         : 2918   
  of which 6 byte RBA <11 NFM:    0   
  of which 6 byte RBA Basic  :    0   
  of which ten byte RBA      : 4293   
Number of TP in BRF          :   17 MMM
.
.
LULIST entries found         :    0   
LUMODES entries found        :    1 MMM
LUNAMES entries found        :    2 MMM
MODESELECT entries found     :    1 MMM
.
.
Total number of REORGs        21          
     REORGing                176 Cylinders
        also requiring      1409 REBINDs


Naturally, most of this is the Db2 Catalog and Directory. At the end it outputs a small list of KPIs with the Total number of REORGs required, the total numbers of Cylinders of space all the table and indexspaces take and how many REBINDs should then be done afterwards. This gives the experienced DBA a very good idea of how long and how potentially dangerous this whole thing could be!

Just the Facts, Ma’am!

Under DD card ALTERCAT in the pay-ware version are all the required actions, note that you must be at Db2 13 FL509 or above to get the CONVERTUTS REORG syntax:

-- REORG TABLESPACE DSNDB01.SCT02 SHRLEVEL CHANGE
--   CONVERTUTS 
-- REORG TABLESPACE DSNDB01.SYSUTILX SHRLEVEL CHANGE
--   CONVERTUTS 
-- REORG TABLESPACE DSNDB06.SYSALTER SHRLEVEL CHANGE
--   CONVERTUTS
-- REORG TABLESPACE DSNDB06.SYSCONTX SHRLEVEL CHANGE
--   CONVERTUTS 
--REBIND PACKAGE(IQA_COLLECTION_610.SQLDVDRC) APREUSE(WARN)       
--REBIND PACKAGE(IQA_COLLECTION_610.SQLDVDRC.(2026-01-21-06.55.23.099777)) APREUSE(WARN)
--REBIND PACKAGE(IQA_COLLECTION_DE.SQLDDLS.(2019-03-22-09.20.33.799998)) APREUSE(WARN)
--REBIND PACKAGE(IQA_COLLECTION_DE.SQLDDLS.(2022-08-01-06.08.43.796175)) APREUSE(WARN)
--REBIND PACKAGE(IQA_COLLECTION_DE.SQLDVCRC.(2018-08-21-07.21.16.927191)) APREUSE(WARN)
--REBIND PACKAGE(IQA_COLLECTION_DE.SQLDVDRC.(2022-08-01-06.21.52.371116)) APREUSE(WARN)
                                    

Notice that it always generates APREUSE(WARN) to try and keep the old access path.

Also, here are any of the nasty DEFINE NO REORG problems:

-- DEFINE NO TABLESPACE TS5941.TSTSDNQ REORG NOT POSSIBLE

and the SQL for CDB Clean-up:

-- DELETE FROM SYSIBM.LUMODES  
-- ;                           
-- COMMIT ;                    
-- DELETE FROM SYSIBM.LUNAMES  
-- WHERE NOT LUNAME = '        '
-- ;                           
-- COMMIT ;                    
-- DELETE FROM SYSIBM.MODESELECT
-- ;                           
-- COMMIT ;
  

Under DD card MIGRAREP are all the Migration Blockers listed out in detail:

Simple DB: DSNDB01 TS: SCT02      
Segmented DB: DSNDB01 TS: SYSUTILX
Segmented DB: DSNDB06 TS: SYSALTER
Segmented DB: DSNDB06 TS: SYSCONTX
Segmented DB: DSNDB06 TS: SYSDDF  
Segmented DB: DSNDB06 TS: SYSEBCDC
Simple DB: DSNDB06 TS: SYSGPAUT   
Segmented DB: DSNDB06 TS: SYSGRTNS
Segmented DB: DSNDB06 TS: SYSHIST 
Segmented DB: DSNDB06 TS: SYSJAVA 
Segmented DB: DSNDB06 TS: SYSROLES
Segmented DB: DSNDB06 TS: SYSSEQ  
Segmented DB: DSNDB06 TS: SYSSEQ2 
Segmented DB: DSNDB06 TS: SYSSTATS
Segmented DB: DSNDB06 TS: SYSTARG 
Segmented DB: DSNDB06 TS: SYSTSASC
Segmented DB: DSNDB06 TS: SYSTSUNI
Segmented DB: DSNDB06 TS: SYSTSXTM
Segmented DB: DSNDB06 TS: SYSTSXTS
Simple DB: DSNDB06 TS: SYSUSER    
Segmented DB: DSNDB06 TS: SYSXML  
Segmented DB: TS5941 TS: TSTSDNQ  
Segmented DB: WRKSD10 TS: DSN32K00
Segmented DB: WRKSD10 TS: DSN32K01
Segmented DB: WRKSD10 TS: DSN4K00 
Segmented DB: WRKSD10 TS: DSN4K01 
Segmented DB: WRKSD11 TS: DSN32K00
Segmented DB: WRKSD11 TS: DSN32K01
Segmented DB: WRKSD11 TS: DSN4K00 
Segmented DB: WRKSD11 TS: DSN4K01 
BRF tablespace DB: DSNDB01 TS: SCT02    
BRF tablespace DB: DSNDB01 TS: SYSUTILX 
BRF tablespace DB: DSNDB06 TS: SYSALTER 
BRF tablespace DB: DSNDB06 TS: SYSCONTX  
BRF tablespace DB: DSNDB06 TS: SYSDDF    
BRF tablespace DB: DSNDB06 TS: SYSEBCDC  
BRF tablespace DB: DSNDB06 TS: SYSGPAUT  
BRF tablespace DB: DSNDB06 TS: SYSGRTNS  
BRF tablespace DB: DSNDB06 TS: SYSHIST   
BRF tablespace DB: DSNDB06 TS: SYSJAVA   
BRF tablespace DB: DSNDB06 TS: SYSROLES  
BRF tablespace DB: DSNDB06 TS: SYSSEQ    
BRF tablespace DB: DSNDB06 TS: SYSSEQ2   
BRF tablespace DB: DSNDB06 TS: SYSSTATS  
BRF tablespace DB: DSNDB06 TS: SYSTARG   
BRF tablespace DB: DSNDB06 TS: SYSUSER   
BRF tablespace DB: DSNDB06 TS: SYSXML    
CDB table LUMODES has row - LUNAME DKLTEST MODENAME MODTEST.
CDB table LUNAMES has row - LUNAME DKLTEST SYSMODENAME MODTEST.
CDB table LUNAMES has row - LUNAME ROYTEST SYSMODENAME -none-.
CDB table MODESELECT has row - LUNAME DKLTEST AUTHID DKLTEST_AUTH_ID PLANNAME DKLTEST.

Note the WRKxxxx tablespaces…

Start to plan today!

Using our MigrationReadiness HealthCheck for Db2 z/OS freeware you can start to divvy up and plan all of the work that will be coming down the vNext road towards you. Start now and you still have over two years to get it all done and actioned. Start in two years and you will never make it – The choice is yours!

TTFN,

Roy Boxwell
2026-01 Things I learnt last year…

Hi all! This month I wish to go though a few of the interesting, annoying and odd things that I bumped into last year. Some were new for me and some were just interesting for me!

COMPRESS THIS!

One of my customers is now starting down the road of compressing their very, very large NPSI’s as the RECOVER utility is actually way faster than a REBUILD. Nothing new here, is there? But wait! What if they are using FLASH COPY?

It gets very, very ugly very, very quickly is what happens!

Why?

Remember how FLASH COPY works? It is sooooo blindingly fast because it does all the actual copy stuff „in the DS8000, or equivalent, box“ and *not* on your mainframe. This is really cool as you just shoot off a FLASH COPY and, as long as a few really basic rules are not broken, the copy is finished the moment it starts!

So, what about Indexes?

Firstly, if you want to do a FLASH COPY of a COMPRESS YES index you *cannot* also do a sequential copy. Further, remember that a FLASH COPY is a VSAM dataset and you cannot do a COPYTOCOPY of one of these either, meaning you have just one single VSAM dataset as a copy – This is, at least for me, a single point of failure and not good. But it gets much worse!

Really, how so?

Please now remember how index compression works… It is done purely „in memory“ in the bufferpool. This means that when you have an insert, delete, or key update in memory and it has not yet been externalized to disk that when you now do a FLASH COPY you are copying garbage… This is, to coin a phrase, „not good“ whereas a normal COPY index goes through the bufferpool and so a sequential copy is naturally ok!

Bottom Line

If using COMPRESS YES indexes in no way use FLASH COPY. Perhaps, at least for storage, dataset compression of the sequential copy datasets might save space…but then that defeats the purpose of COMPRESS YES on the index purely in the Db2 world which is primarily reducing I/O and secondarily reducing index page splits.

What about SYSTEM LEVEL BACKUPS?

Guess what? These are FLASH COPY as well! If you use SLBs and you have COMPRESS YES indexes you better be careful what you „replay“ and make sure to always REBUILD, or at least CHECK, all indexes after a RECOVER has been run!

Docu?

All of the above is documented of course but it is like Douglas Adams wrote „in the bottom of a locked filing cabinet stuck in a disused lavatory with a sign on the door in saying ‚Beware of the Shark.'“ – [The Shark is my idea geddit? Originally it was Leopard of course!]

Death By RUNSTATS

It is surprisingly easy to kill yourself with a simple RUNSTATS these days.

How?

Let’s say you have PROFILE on and you are using SYSSTATFEEDBACK for all your tables. I know you are as it is all on by default and who changes defaults?

And?

Now a third-party vendor sells you some software with ridiculously long VARCHAR fields containing possible NAMEs and ADDRESSes. In this case VARCHAR(2000) is being used. The SQL in question is using dynamic SQL with literals, not parameter markers, in the WHERE clause against these columns and SYSSTATFEEDBACK „sees“ the requirement for column groups as these columns have, naturally, no index and a column group is a „poor man’s“ index for frequencies and cardinalities, right?

So?

You end up with 23 column groups for a five partition table with over 120 million rows.

But what has that got to do with the Price of Beef?

So, dear, friends, what does our poor old RUNSTATS utility do now? It must farm out these column groups to DFSORT — and can you guess how it works out the allocation size??? You guessed it: 2000 + 8 for the maximum record size then multiplied by 23, for the number of column groups, then the result multiplied by the number of rows: 120,000,000. Do the math and you end up with a DFSORT storage requirement of over 5 PB (Yep that’s PETA bytes!), then the Storage Admin freaked out!

Easy fix: Delete all COLGROUP definitions for this table not backed by a real index. RUNSTATS DELETE PROFILE is a great help here! Then switch off SYSSTATFEEDBACK for this table and control *all* other column groups because as I like to say „where there is one, there are probably more“.

Bugblatter Beast of Traal

It is possible to wrap your head in a towel so the beast does not see you, but it is sometimes better to actually look for these things before they get really really bad. I hate to think how long this RUNSTATS was just „growing and growing and growing“ with no-one noticing that it was quite simply insane!

SYSSTATFEEDBACK is good but not that good!

Remember, it is doing the best it can based on the SQL usage and what the Db2 Optimizer thinks is missing or might improve performance. In this case, the excessive number of column groups and the excessive size of the groups was actually way more of a problem than a help!

Parameter Markers…

It would also have been fine if the developers had coded good SQL with parameter markers so that SYSSTATFEEDBACK would not have started the whole problem in the first place! As a secondary bonus, moving to parameter markers stops any SQL Injection attack vectors as you could do a lot of damage with a VARCHAR(2000) text field!!! Just using „A‘ OR ‚A‘ = ‚A“ would be nice and evil, wouldn’t it!!! Returns every single row because in the code it is stringed into a delimited string. So, if the customer gives A as input it builds this string:

SELECT all my columns FROM mytable WHERE ADDRESS = 'A' ;

Now add my injection code:

SELECT all my columns FROM mytable WHERE ADDRESS = 'A' OR 'A' = 'A' ;

What does that OR do? Yep – It is always true so every row is always returned…Not what you would want with 120 million rows…

Stale Stats?

A last bit about SYSSTATFEEDBACK is that it recommends STALE quite a lot and some of these bogus entries are, in fact, just created by a STALE recommendation so one other way of clearing them all out is to run a little SQL like the following:

-- THIS SQL WILL CORRECT THE PROBLEM OF BOGUS COLUMN COLGROUP CAUSING
-- EXCESSIVE SORT ALLOCATION AND FAILING RUNSTATS.
--
-- WHAT IT DOES IS:
--
--  1) STOP SYSSTATFEEDBACK GENERATION FOR A GIVEN TABLE
--  2) CLEAN UP SYSCOLDIST AND SYSCOLDISTSTATS "F" ENTRIES WHICH
--    ARE LISTED IN SYSSTATFEEDBACK WITH A "F" AND "STALE" ENTRY
--  3) DELETE ALL "F" AND "STALE" ENTRIES FROM SYSSTATFEEDBACK
--
-- TWO VARIABLES WILL BE CREATED AND USE THE DEFAULT FOR NAME AND
-- CREATOR:
--
CREATE VARIABLE TAB_NAME    VARCHAR(128)
   DEFAULT 'MY_BAD_TABLE'
;
CREATE VARIABLE TAB_CREATOR VARCHAR(128)
   DEFAULT 'MY_BAD_CREATOR'
;
--
-- STOP SYSSTATFEEDBACK PROCESSING FOR THIS TABLE
--
UPDATE SYSIBM.SYSTABLES
SET STATS_FEEDBACK = 'N' 
WHERE CREATOR      = TAB_CREATOR
  AND NAME         = TAB_NAME
  AND TYPE         = 'T'
;
COMMIT ;
--
-- DELETE ANY STALE COLDIST FREQ VALS FOR THIS TABLE
--
DELETE FROM SYSIBM.SYSCOLDIST A
WHERE A.TBOWNER    = TAB_CREATOR 
  AND A.TBNAME     = TAB_NAME
  AND A.TYPE       = 'F'
  AND EXISTS (SELECT 1 FROM SYSIBM.SYSSTATFEEDBACK B
              WHERE B.TBCREATOR = TAB_CREATOR
                AND B.TBNAME    = TAB_NAME
                AND B.TYPE      = 'F'
                AND B.REASON    = 'STALE'
                AND B.TBCREATOR = A.TBOWNER
                AND B.TBNAME    = A.TBNAME
                AND B.COLNAME   = A.NAME)
;
COMMIT ;
--
-- DELETE ANY STALE COLDISTSTATS FREQ VALS FOR THIS TABLE
--
DELETE FROM SYSIBM.SYSCOLDISTSTATS A
WHERE A.TBOWNER    = TAB_CREATOR
  AND A.TBNAME     = TAB_NAME
  AND A.TYPE       = 'F'
  AND EXISTS (SELECT 1 FROM SYSIBM.SYSSTATFEEDBACK B
              WHERE B.TBCREATOR = TAB_CREATOR
                AND B.TBNAME    = TAB_NAME
                AND B.TYPE      = 'F' 
                AND B.REASON    = 'STALE'
                AND B.TBCREATOR = A.TBOWNER
                AND B.TBNAME    = A.TBNAME
                AND B.COLNAME   = A.NAME)
;
COMMIT ;
--
-- DELETE ANY STALE SYSSTATFEEDBACK FREQ VALS FOR THIS TABLE
--
DELETE FROM SYSIBM.SYSSTATFEEDBACK
WHERE TBCREATOR    = TAB_CREATOR
  AND TBNAME       = TAB_NAME
  AND TYPE         = 'F'
  AND REASON       = 'STALE'
;
COMMIT ;
--
-- DROP THE CREATED VARS FOR NEXT RUN
--
DROP VARIABLE TAB_NAME    ;
DROP VARIABLE TAB_CREATOR ;
COMMIT ;

Take care out there!

Caveat Emptor!

Remember to always review DELETEs like this *before* you do them in production. Blindly deleting stuff is sometimes dangerous and hazardous to your career path!

I hope you found this info interesting on a cold and dark January day, at least here in Germany!

TTFN,

Roy Boxwell

2020-01 How RUNSTATS causes an error SQLCODE

Impossible! I hear you all say… How can a RUNSTATS *cause* an SQL error code? Well, my gentle readers, read on.


Two examples in SPUFI at the end of this newsletter

What we know

We are all, I hope, aware that a badly timed RUNSTATS can cripple your SQL Performance. Just think of a see-sawing, or volatile table, and it gets a RUNSTATS at the zero point… Tablespace scan is then a good access choice… After a couple of million inserts that is probably not the best!

Awful, Implicit Casting

Implicit casting came along a few Db2 releases ago and either made you very happy: “I never have to worry about using apostrophes again!” or very angry: “Developers must know what they are coding!” The thing is, we got it and you cannot *not* do it!

It goes both ways…

The idea behind Implicit casting, in case you don’t know, is that :

The predicate COL1 = 1 and COL1 = ‘1’ are the same to Db2.

It will take that ‘1’ and “cast” it to a variable type that will then be able to be compared to whatever type COL1 is.

So,

  • if COL1 contains a numeric representation of data everything is ok.
  • But if COL1 is CHAR(1) and contains a ’Y’ you then get an SQLCODE -420

Nasty, nasty business…

Access path is also sub-optimal

When Db2 does implicit casting, it casts to DECFLOAT to then do the comparison etc. (See my DECFLOAT newsletter about what I think about that data type!) Anyway, it is *not* good for performance. In fact, it got so annoying that a few users actually asked for a ZPARM to switch off implicit casting! They actually wanted an error whenever they compared mismatched data types. This request was, of course, turned down.

So where’s the beef?

So, what happened in production was quite simple really:

A query had been running for three years with never a problem. Then one day, after a RUNSTATS, it started returning SQLCODE -420. This was due to the fact that the table processing order had switched, due to the RUNSTATS running at a “bad” time.

This in turn exposed the buggy SQL WHERE predicate that previously had never seen the bad data as it was removed in an earlier branch! This could also happen when the column in question actually contains non-numeric data perhaps dues to a code bug .

See the example SQL at the end  

RUNSTATS Rescue for Db2 z/OS

This user site has our software RUNSTATS Rescue so they quickly got the query up and running, without doing a code change, in a matter of seconds.

Of course, this bad code was discovered in the middle of the year end production freeze so they could not simply change the application code! This code change has been scheduled and will be done in the new year.

Bottom Line

RUNSTATS can cause negative SQLCODEs to be returned and RUNSTATS Rescue buys you the needed time to continue running – even with buggy SQL code!

As always, I would be pleased to hear from you and any war stories you have!

TTFN,
Roy Boxwell
Senior Architect


PS: Just for the record, here are two examples in SPUFI:


 SELECT *
 FROM SYSIBM.SYSDUMMY1                                                  
 WHERE IBMREQD = '1'                                                   
 ;                                                                      
 ---------+---------+---------+---------+---------+---------+---------+-
 IBMREQD                                                                
 ---------+---------+---------+---------+---------+---------+---------+-
 DSNE610I NUMBER OF ROWS DISPLAYED IS 0                                 
 DSNE616I STATEMENT EXECUTION WAS SUCCESSFUL, SQLCODE IS 100            
 ---------+---------+---------+---------+---------+---------+---------+-
 SELECT *                                                               
 FROM SYSIBM.SYSDUMMY1                                                  
 WHERE IBMREQD = 1                                                      
 ;                                                                      
 ---------+---------+---------+---------+---------+---------+---------+-
 IBMREQD                                                                
 ---------+---------+---------+---------+---------+---------+---------+-
 DSNE610I NUMBER OF ROWS DISPLAYED IS 0                                 
 DSNT408I SQLCODE = -420, ERROR:  THE VALUE OF A STRING ARGUMENT WAS NOT
          ACCEPTABLE TO THE DECFLOAT FUNCTION     
 DSNT418I SQLSTATE   = 22018 SQLSTATE RETURN CODE                        
 DSNT415I SQLERRP    = DSNXRNUM SQL PROCEDURE DETECTING ERROR            
 DSNT416I SQLERRD    = -245 0  0  -1  0  0 SQL DIAGNOSTIC INFORMATION    
 DSNT416I SQLERRD    = X'FFFFFF0B'  X'00000000'  X'00000000'  X'FFFFFFFF'
          X'00000000'  X'00000000' SQL DIAGNOSTIC INFORMATION            

And the result when the column actually contains a numeric valid value and not “Y”:

CREATE TABLE BOXWELL.SYSDUMMY1 LIKE SYSIBM.SYSDUMMY1       
 ;                                                          
 ---------+---------+---------+---------+---------+---------
 DSNE616I STATEMENT EXECUTION WAS SUCCESSFUL, SQLCODE IS 0  
 ---------+---------+---------+---------+---------+---------
 INSERT INTO  BOXWELL.SYSDUMMY1 VALUES ('1')                
 ;                                                          
 ---------+---------+---------+---------+---------+---------
 DSNE615I NUMBER OF ROWS AFFECTED IS 1                      
 DSNE616I STATEMENT EXECUTION WAS SUCCESSFUL, SQLCODE IS 0  
 ---------+---------+---------+---------+---------+---------
 SELECT *                                                   
 FROM BOXWELL.SYSDUMMY1                                     
 WHERE IBMREQD = '1'                                        
 ;                                                          
 ---------+---------+---------+---------+---------+---------
 IBMREQD                                                    
 ---------+---------+---------+---------+---------+---------
 1                                                          
 DSNE610I NUMBER OF ROWS DISPLAYED IS 1                     
 DSNE616I STATEMENT EXECUTION WAS SUCCESSFUL, SQLCODE IS 100
 ---------+---------+---------+---------+---------+---------
 SELECT *                                                   
 FROM BOXWELL.SYSDUMMY1                                     
 WHERE IBMREQD = 1                                          
 ;                                                          
 ---------+---------+---------+---------+---------+---------
 IBMREQD                                                    
 ---------+---------+---------+---------+---------+---------
 1                                                          
 DSNE610I NUMBER OF ROWS DISPLAYED IS 1
 DSNE616I STATEMENT EXECUTION WAS SUCCESSFUL, SQLCODE IS 100

Cool and dangerous! Just like me! LoL ! ! !

2018-03 RTS RUNSTATS

„Breaking the rules is often fun, although we cannot condone it. But breaking the rules of Real Time Statistics (RTS) in Db2 12 can really land you in hot water.

We provide two queries that may give you a Get Out of Jail Free Card – at least as far as RTS is concerned…”

In this short newsletter, I wish to briefly discuss a change in behavior of the Real Time Statistics (RTS) tables that I have now seen at customer sites. I am not too happy about it! Before we start, a quick resumé of the RTS is required.

The Arrival of RTS

The Real Time Statistics were basically created by Dr Jim Teng in Db2 V7 and have always obeyed a few quite simple rules.


Real Time Statistics (RTS) rules:


  1. Rule Number one
    If in doubt set to NULL.
    This might read a bit odd but the idea from Jim was that if any value is not 100% known then the column must be set to the NULL value.


  2. Rule Number two
    Externalize when asked, or by timer.


  3. Rule Number three
    No DEFINE NO data.


  4. Rule Number four
    Utilities will always update the RTS unless it cannot – see Rule Number one.


  5. Rule Number five
    SQL updates the counters unless they cannot – Think Mass Delete in a multi-table tablespace. Totalrows cannot be updated.

Rules are made to be broken

A couple of years into RTS usage and the clamor for changing various insert values got too big, so IBM enhanced the RTS so that on creation the REORGLASTTIME got set to the created timestamp and all the counter columns got set to zero instead of NULL. Now this was a good change as adding 1,000,000 to NULL you get NULL, whereas adding 1,000,000 to zero means you get 1,000,000 which is obviously better for working out whether or not you need a utility to run. The REORGLASTTIME was also accepted as when you create a nice empty object or you insert one row into an object, then by definition, it is in a perfectly reorganized state!

RTS rule one broken

Mass delete always caused problems, as mentioned earlier, so IBM then made a “half way” fix for the INDEX statistics in Db2 9 by zeroing the TOTALENTRIES when there is a Mass Delete as Db2 knows that the index is now empty.

(PM34730: RTS SYSINDEXSPACESTATS TOTALENTRIES INCORRECT AFTER MASS DELETE.)

Of course it did not update the TOTALROWS, as it didn’t “know” how many rows were mass deleted or truncated. This causes “drift” between the TS and IX statistics, but is only a minor annoyance.

Db2 12 breaks rule one

Now in Db2 12 Rule one has been broken again. Not that much of a break, but still not brilliant! What they have done, is change the STATSLASTTIME to now also be, nearly, the created TS – as if creating an object sets the runstats columns to valid data!

Naturally, the Db2 Catalog is still all -1’s. This makes generating utilities based on the RTS a little bit tricky, as you cannot trust the STATSLASTTIME to now ever actually be the time a RUNSTATS utility really ran – which was the *whole*, and only, purpose of this column! If only they had set the STATSLASTTIME to ‘0001-01-01-00.00.00.00.000000’ then all would be well…

Who woke the dogs up? (Or: Who let the dogs out? I.e. American jargon)

PI79234: SYSIBM.SYSTABLESPACESTATS.STATSINSERTS IS NOT UPDATED BY RTS EXTERNALIZATION SINCE OBJECT IS CREATED.
Is the APAR (PTF UI48494) that caused me all the trouble.

Where’s the beef?

Well, the problem is, if you are generating RUNSTATS based on the RTS – and who isn’t these days? – Then you are probably using this column. Now it *looks* like a RUNSTATS has been run at least once.

This is false and can lead to the not running of RUNSTATS when it most definitely should have been run. Check all your home-grown RUNSTATS checkers. Remember DSNACCOX is also a little bit broken, as it uses these predicates:

(STATSLASTTIME IS NULL OR
 STATSLASTTIME<LOADRLASTTIME OR
 STATSLASTTIME<REORGLASTTIME OR
 STATSLASTTIME< latest PROFILE_UPDATE for the table space1 OR

Make sure you do not use the STATSLASTTIME, but instead join across to the SYSINDEXPART or SYSTABLEPART and pull out the STATSTIME column. This data is still ok and not fake news!

The scope of the problem

To find out the scope of the problem at your site, or even if you have this problem, you can run these two queries which simply list out all the objects that have, according to the Db2 Catalog, never been RUNSTATted, but according to the RTS they have been RUNSTATted:

Query 1

-- SELECT LIST OF TABLESPACES THAT ACCORDING TO DB2 CATALOG HAVE NOT 
-- BEEN RUNSTATTED BUT ACCORDING TO RTS HAVE BEEN.  
-- IGNORE DSNDB01 AS NO RUNSTATS FOR DIRECTORY OBJECTS 
-- IGNORE WORK DEFINED DATABASES AS NO RUNSTATS FOR THESE 
-- ONLY CHECK FOR TABLE TYPES H,M,P,R AND T 
-- DISTINCT IT FOR MULTI TABLE TABLESPACES 
SELECT DISTINCT A.DBNAME, A.NAME, A.PARTITION 
      ,A.REORGLASTTIME, A.STATSLASTTIME 
      ,B.STATSTIME, B.CREATEDTS 
FROM SYSIBM.SYSTABLESPACESTATS A 
   ,SYSIBM.SYSTABLEPART        B 
   ,SYSIBM.SYSDATABASE         C 
   ,SYSIBM.SYSTABLES           D 
WHERE   B.STATSTIME       = TIMESTAMP('0001-01-01-00.00.00.000000') 
  AND NOT COALESCE(A.STATSLASTTIME 
                           ,TIMESTAMP('0001-01-01-00.00.00.000000')) 
                          = TIMESTAMP('0001-01-01-00.00.00.000000') 
  AND NOT A.DBNAME        = 'DSNDB01' 
  AND A.DBNAME            = C.NAME 
  AND NOT C.TYPE          = 'W' 
  AND A.DBNAME            = B.DBNAME 
  AND A.NAME              = B.TSNAME 
  AND A.PARTITION         = B.PARTITION 
  AND A.DBNAME            = D.DBNAME 
  AND A.NAME              = D.TSNAME 
  AND D.TYPE            IN ('H' , 'M' , 'P' , 'R' , 'T') 
ORDER BY 1 , 2 , 3 
; 

Query 2

-- SELECT LIST OF INDEXSPACES THAT ACCORDING TO DB2 CATALOG HAVE NOT 
-- BEEN RUNSTATTED BUT ACCORDING TO RTS HAVE BEEN. 
-- IGNORE DSNDB01 AS NO RUNSTATS FOR DIRECTORY OBJECTS 
-- IGNORE HASH INDEXES AS NO RUNSTATS ALLOWED 
-- ONLY CHECK FOR TABLE TYPES H,M,P,R AND T 
SELECT A.DBNAME, A.INDEXSPACE, A.PARTITION 
      ,A.REORGLASTTIME, A.STATSLASTTIME 
      ,B.STATSTIME, B.CREATEDTS 
FROM SYSIBM.SYSINDEXSPACESTATS A 
    ,SYSIBM.SYSINDEXPART       B 
    ,SYSIBM.SYSINDEXES         C 
    ,SYSIBM.SYSTABLES          D 
WHERE   B.STATSTIME       = TIMESTAMP('0001-01-01-00.00.00.000000') 
  AND NOT COALESCE(A.STATSLASTTIME 
                          ,TIMESTAMP('0001-01-01-00.00.00.000000')) 
                          = TIMESTAMP('0001-01-01-00.00.00.000000') 
  AND NOT A.DBNAME        = 'DSNDB01' 
  AND A.CREATOR           = B.IXCREATOR 
  AND A.NAME              = B.IXNAME 
  AND A.PARTITION         = B.PARTITION 
  AND A.CREATOR           = C.CREATOR 
  AND A.NAME              = C.NAME 
  AND NOT C.HASH          = 'Y' 
  AND C.TBCREATOR         = D.CREATOR 
  AND C.TBNAME            = D.NAME 
  AND D.TYPE            IN ('H' , 'M' , 'P' , 'R' , 'T') 
ORDER BY 1 , 2 , 3 -
;

You can run these in any version of Db2 you like, but you will only get results from a Db2 12 system with this APAR applied and you have created an index or a tablespace. When I run them here on my Db2 10 and 11 systems I get zero rows back and on my test Db2 12 FL501 system I get 172 rows.

The good news is…

Our product for helping you all get “agile” in Db2 12, CDDC – ContinuousDelivery DeploymentCheck, detects and reports these data constellations as does our Statistics Health Check, of course.

I would be very interested to hear your opinions about this “little change in behavior”. Have you come across this at your site?


As always, any questions or comments would be most welcome!

TTFN,

Roy Boxwell

2018-02 Db2 Catalog Statistics revisited

Db2 Optimizer & access path selection for Db2 11 & Db2 12 :

Db2 Catalog dataProblematic default values | Correlations in the Db2 Catalog 

It has been six years since the last update so I thought, after Terry Purcell’s excellent presentation in January 2018, it would be a good point in time to go over and rake the coals again—especially as a couple of things have changed for Db2 12!


Terry Purcell – Db2 12 for z/OS Optimizer and RUNSTATS improvements
Webcast replay          Abstract

Are you a RUNSTATS Master?

Every now and again, I hold a little presentation called “Are you a RUNSTATS Master?” Actually these days it’s called “Db2 z/OS Lies, Damn Lies, and Statistics…” where I describe in detail, what the Db2 Optimizer uses for access path selection in relation to the Db2 Catalog data.

Surprised? You will be!

Personally, I am always surprised at how often people say “just that data?” or “is that it?” (the various other reasons for access path selection like CP speed, RID Pool size, Sort Pool size, Max data caching size, and, of course, the 80 bufferpools are also mentioned, but these have nothing to do with RUNSTATS).

So generally the answer is “Yes.” However, the permutations and combinations make the devil in the detail – The Db2 Optimizer’s algorithms are top secret, but the input data it uses is fully described in the documentation.

Just the facts ma’am

What I want to do, is show :

  • the Db2 Catalog data that is used
  • the default values that can cause surprising things to happen
  • the problem of correlations in the Db2 Catalog

Which data are used by the Db2 Optimizer and which are updated by RUNSTATS?

Here is a complete list of the eleven tables used by the Db2 Optimizer:

  1. SYSIBM.SYSCOLDIST
  2. SYSIBM.SYSCOLSTATS *
  3. SYSIBM.SYSCOLUMNS
  4. SYSIBM.SYSINDEXES
  5. SYSIBM.SYSINDEXPART
  6. SYSIBM.SYSKEYTARGETS (same as SYSCOLUMNS)
  7. SYSIBM.SYSKEYTGTDIST (same as SYSCOLDIST)
  8. SYSIBM.SYSROUTINES
  9. SYSIBM.SYSTABLES
  10. SYSIBM.SYSTABLESPACE
  11. SYSIBM.SYSTABSTATS

* degree of parallelism only and, after APAR PK62804, also „sometimes“ used to bound filter factor estimates…

By the Columns

Now we can also list out all of the columns (obviously not including the key columns) which are used by the Db2 Optimizer:


SYSCOLDIST
CARDF, COLGROUPCOLNO, COLVALUE, FREQUENCYF, HIGHVALUE, LOWVALUE, NUMCOLUMNS, QUANTILENO, STATSTIME


SYSCOLSTATS
COLCARD, HIGHKEY, LOWKEY


SYSCOLUMNS
COLCARDF, HIGH2KEY, LOW2KEY


SYSINDEXES
CLUSTERING*, CLUSTERRATIO, CLUSTERRATIOF, DATAREPEATFACTORF, FIRSTKEYCARDF, FULLKEYCARDF, NLEAF, NLEVELS


SYSINDEXPART
LIMITKEY*


SYSKEYTARGETS
CARDF, HIGH2KEY, LOW2KEY, STATS_FORMAT


SYSKEYTGTDIST
CARDF, KEYGROUPKEYNO, KEYVALUE, FREQUENCYF, HIGHVALUE, LOWVALUE, NUMKEYS, QUANTILENO, STATSTIME


SYSROUTINES
CARDINALITY*, INITIAL_INSTS*, INITIAL_IOS*, INSTS_PER_INVOC*, IOS_PER_INVOC*


SYSTABLES
CARDF, EDPROC*, NPAGES, NPAGESF, PCTROWCOMP


SYSTABLESPACE
NACTIVE, NACTIVEF


SYSTABSTATS
CARD, CARDF, NPAGES


Notes: * Columns are not updated by RUNSTATS and _ Columns are not updatable at all. The column STATSTIME is used only if there are duplicates in the SYSCOLDIST table, and then the Db2 Optimizer will use the “newer” data that was probably inserted by a User.

Know your defaults

Which default column values trigger the Db2 Optimizer to use its own internal default values?


SYSCOLUMNS


If COLCARDF                       = -1 then use 25


SYSINDEXES


If CLUSTERRATIOF            = 0 then use CLUSTERRATIO


If CLUSTERRATIO              = 0 then use 0.95 if the index is CLUSTERing = ‘Y’ otherwise 0.00


DATAREPEATFACTORF    = -1 then is ignored


If FIRSTKEYCARDF            = -1 then use 25


If FULLKEYCARDF             = -1 then use 25


If NLEAF                              = -1 then use 33 (Which is SYSTABLES.CARDF / 300)


If NLEVELS                         = -1 then use 2


SYSROUTINES


If CARDINALITY                  = -1 then use 10,000  


If INITIAL_INSTS                 = -1 then use 40,000


If INITIAL_IOS                     = -1 then use 0


If INSTS_PER_INVOC        = -1 then use 4,000


If IOS_PER_INVOC            = -1 then use 0


If IOS_PER_INVOC            = -1 then use 0


SYSTABLES


If CARDF                             = -1 then use 10,000


If NPAGESF                      <= 0 then use NPAGES


If NPAGES                          = -1 then use 501 (Which is CEILING (1 + SYSTABLES.CARDF / 20))

Here you must be very careful if using NPGTHRSH ZPARM as 501 is more than the default value in most shops. This is one of the little changes in Db2 12 where the value -1 is treated as -1 for the NPGTHRSH check.


SYSTABLESPACE


If NACTIVEF                     = 0 then use NACTIVE


If NACTIVE                       = 0 then use 501 (Which is CEILING (1 + SYSTABLES.CARDF / 20))


SYSTABSTATS


If CARDF                         = -1 then use 10,000


If NPAGES                       = -1 then use 501 (Which is CEILING (1 + SYSTABSTATS.CARDF / 20))


So now you can see that non-floating point “old” data, may still be used today and this may cause access path headaches!

Never ever say never

Now to top it all, the data in the SYSCOLDIST and SYSKEYTGTDIST never gets simply “deleted”.

Well, actually, in Db2 12 you can now do a RUNSTATS xxx.yyy RESET ACCESSPATH to delete all SYSCOLDIST and SYSKEYTGTDIST data and set all other relevant columns to their respective defaults, but you must time this RUNSTATS very wisely! If you run it and then forget to do a normal full RUNSTATS…

Oldie but a goldie

Once the data are inserted, they stay there, until they are overwritten by new data, a RUNSTATS RESET, or the object is dropped. This all leads to some very old data in these two tables that can and do cause the Db2 Optimizer a ton of grief! One of the first things I do is to simply select the MIN(STATSTIME) from these tables just to see how old the data really is. Do it yourself and be surprised! I have seen sites with eight-year old data in the SYSCOLDIST and that cannot be good!

Correlate the world

Now onto correlations… There are lots of little tricks that DBAs use to “massage” access path choice. One of these, is to just set NLEVELS to 15 for a given index. Then lots of queries simply refuse to touch it as it would appear to be HUGE. Now, just simply updating columns can cause the Db2 Optimizer, in the best case, to ignore the updates or, perhaps, makes things even worse! So here is a list of the correlations (In other words, if you change xxx remember to change yyy and zzz as well):

Relationships exist among certain columns of certain tables:

  •       Columns within SYSCOLUMNS
  •       Columns in the tables SYSCOLUMNS and SYSINDEXES
  •       Columns in the tables SYSCOLUMNS and SYSCOLDIST
  •       Columns in the tables SYSCOLUMNS, SYSCOLDIST, and SYSINDEXES

 If you plan to update some values, keep in mind the following correlations:

  •  COLCARDF and FIRSTKEYCARDF/FULLKEYCARDF (They must be equal for the 1st column and full, if a single column index)
  •  COLCARDF, LOW2KEY and HIGH2KEY. (For non-default COLCARDF LOW2KEY and HIGH2KEY key must be filled with data) and if the COLCARDF is 1 or 2 Db2 uses LOW2KEY and HIGH2KEY as domain statistics to generate frequencies.
  • CARDF in SYSCOLDIST.  CARDF is related to COLCARDF and FIRSTKEYCARDF and FULLKEYCARDF. It must be at a minimum
  • A value between FIRSTKEYCARDF and FULLKEYCARDF if the index contains the same set of columns
  • A value between MAX(colcardf of each col) and the product of all the columns COLCARDFs in the group
  • CARDF in SYSTABLES. CARDF must be equal or larger than any other cardinalities, such as COLCARDF, FIRSTKEYCARDF, FULLKEYCARDF, and CARDF in SYSCOLDIST
  • FREQUENCYF and COLCARDF or CARDF. The number of frequencies collected must be less than or equal to COLCARDF for the column or CARDF for the column group
  • FREQUENCYF. The sum of frequencies collected for a column or column group must be less than or equal to 1

New in Db2 11

In Db2 11, the table SYSSTATFEEDBACK was introduced giving us the first chance to see what the optimizer thinks is missing. This is truly awesome, as then we can tailor our RUNSTATS to generate exactly what the optimizer needs to really validate and generate a good, stable access path. Of course, you should be a little bit careful with this data as too much of a good thing can be bad for you!

New in Db2 12

(Not just the lowercase b!)

In Db2 12, the SYSSTATFEEDBACK was made even more interesting by now externalizing the required RUNSTATS options *directly* into the already existing RUNSTATS profile or, indeed, actually creating a RUNSTATS profile for you.

I think that is really dangerous, as then you could easily flood your system with bogus stats for end user QMF/SPUFI queries that were run “by accident,” or so called “boss queries” where someone with *no* idea of SQL clicks together a highly complex and badly written SQL before letting it run for a weekend. Naturally the SQL gets rewritten by a helpful ever present DBA, but the statistics recommendations have now landed in the profile and will be updated and kept from this point on.

My personal recommendation is to switch off this feature as it is sadly *on* by default!

Here are the ZPARMs of interest

ZPARM STATFDBK_SCOPE set to ALL by default.
ZPARM STATFDBK_PROFILE set to YES by default.
Plus, in table SYSIBM.SYSTABLES column STATS_FEEDBACK is set to Y by default.

Out-of-the box it starts automatically creating (for TYPE=’C‘ with NUMCOLS > 1 and TYPE=’F‘ or ‚H‘) profiles and updating existing profiles…Here you must manually check the size of your profiles every now and again just to make sure everything is ok!

One other new thing in Db2 12, is that XML columns can get statistics now to help XMLEXISTS get a better access path.

and finally

Do not forget that our little Freeware tool StatisticsHealthCheck will find all bad correlations, old data and badly updated data for you and it is FREE!

So I hope this little round-up of Db2 Catalog Statistics data was interesting, and, as usual, if you have any comments or questions, then please, feel free to mail me!

TTFN

Roy Boxwell


Southwest Db2 Users Group – Februar 2018

Db2 Forum.  Southwest Db2 Users Group – Februar 2018 – Grapevine (Dallas), TX, USA

SEGUS & SOFTWARE ENGINEERING sponsern diese Veranstaltung & präsentieren 

1 – Pdf Präsentation  –  Compliance with compliments! Viable Db2 z/OS workload tracking.

2 – Pdf Präsentation –   Db2 12 Continuous Delivery – New challenges for deployment.

3 – Pdf Präsentation –   Db2 z/OS Lies, Damn Lies, and Statistics… 


1 – Db2 z/OS Security Audit: Compliance with compliments! Viable Db2 z/OS workload tracking.

Audit and Compliance is a need that many companies want and have to fulfill.

There’s different ways and tools that promise to be able to do it, but what can they really do and what are the associated costs? This presentation introduces Db2 10/11 technology exploitation that delivers any DML, DDL, DCL being executed in a Db2 environment along with identification details. Learn how you can run Audit analytics against a long‐term repository, pinpointing who executed a query, when and from where. Analyze your entire workload to understand access patterns and abnormalities.


Mehr über Db2 Audit

Presentation Outline

  • Audit needs and musts Take a journey to GLB HIPAA PCI‐DSS Basel III Sarbanes‐Oxley CA SB1386 Federal Information Security Management Act “ed Flag”Rules (FRCA)5.
  • Solution overview and their Pros/Cons Get an overview about the existing solutions and understand how they work.
  • The viable way – let Db2 do the magic! Learn about Db2 enhancements in Db2 10/11 that deliver the Db2 workload being processed and understand why it’s so efficient.
  • Customer results from the banking industry Receive some experience from a large banking company and how they successfully replaced their Db2 Audit feature based reporting by a modern SQL tracking and analytics process.


2 – Db2 12 Continuous Delivery – New challenges for deployment.

Fundamental changes in the Db2 z world often lead to concerns. Let’s face it – some changes force us to change! While a Db2 version migration usually took months, or even years, there will be no new Db2 version after 12, but continuous code drops.

This will have a tremendous impact on migration strategies, because we have to find a reliable way to test these code deliveries in a fraction of time. If we make it, Business Divisions will become enthused at how quickly new technology becomes available for new applications. This presentation will describe the difference between Code, Catalog, Function and Application Levels, how you can control them and how you can fallback in case of anomalies. It also illustrates how we still can be pro-active in testing without burning weeks and months.
Learn how to choose from four different levels of testing and a new way of automation. CD-Screening allows you to pick and choose from KPI based test automation. The levels include simple anomaly alerting, access path verification, clone Pre-apply and even workload capture/replay to easily discover different behaviour resulting from a new code Level.


Mehr über Db2 Continuous Delivery – CD

Presentation Outline

Joining this presentation, you’ll learn how to align Continuous Delivery to your Continuous Availability.

  • Agile, Continuous Delivery, DevOps – just buzz words, or new methodologies?
  • Db2 Code, Catalog, Function and Application Levels – differences and dependencies.
  • Activation/Deactivation of new code and how to fallback and when you can’t.
  • Different flavors of (pro-active) CD-Screening and how it can be automated:

* Anomaly alerting based on Incompatibility Change Indicators (ICIs)
* Dyn./Stat.Access Path Change Detection e.g.via Plan Management
* Clone based code change pre-apply exploiting Backup System
* Workload-KPI verification using SQL replay and KPI comparison

Audience Experience:   Intermediate Advanced
Platform:                        Db2 z/OS
Presentation Length:     60 minutes
Presentation Category:  Database Administration Performance Management Db2 Migration


3 – Db2 z/OS Lies, Damn Lies, and Statistics…

– Benjamin Disraeli, Prime Minister of England (1868, 1874-1880)

The above line may, or may not, have been spoken well over 100 years ago, but the need for statistics and, above all else, accurate statistics is more important than ever in the Db2 world of today.


Mehr über Db2 RUNSTATS

Presentation Outline

  • Db2 RUNSTATS basics & catalog tables and Columns used for access path
  • IBM recommendations through the ages : from Db2 V3 to Db2 12
  • Db2 RUNSTATS advanced
  • SYSCOLDIST explained
  • RUNSTATS real world Q&A :
    use of SAMPLE, COLGROUP, PROFILE, REOPT (ONCE), TABLESAMPLE SYSTEM, HISTOGRAM, …
  • RUNSTATS reversal

Speaker biography

Roy Boxwell has more than 32 years of experience in MVS, OS/390, and z/OS environments – 30 of those in Db2. He specializes in installation, migration, and performance monitoring and tuning. Roy leads the SEG development team responsible for the real time database maintenance solutions. He is also an active participant, speaker and contributor on the IDUG Db2 Listserv and sends out a monthly Db2 z/OS Newsletter.

Heart of Texas Db2 Users Group – Februar 2018

HOTDUG – Heart of Texas Db2 User Group – Februar 2018 –  Austin, TX, USA

SEGUS & SOFTWARE ENGINEERING sponsern diese Veranstaltung & präsentieren

1 – Pdf Präsentation : Compliance with compliments! Viable Db2 z/OS workload tracking.

2 Pdf Präsentation : Db2 12 Continuous Delivery – New challenges for deployment.

3 Pdf Präsentation : Db2 z/OS Lies, Damn lies, and Statistics… 


1 – Db2 z/OS Security Audit: Compliance with compliments! Viable Db2 z/OS workload tracking.

Audit and Compliance is a need that many companies want and have to fulfill.

There’s different ways and tools that promise to be able to do it, but what can they really do and what are the associated costs? This presentation introduces Db2 10/11 technology exploitation that delivers any DML, DDL, DCL being executed in a Db2 environment along with identification details. Learn how you can run Audit analytics against a long‐term repository, pinpointing who executed a query, when and from where. Analyze your entire workload to understand access patterns and abnormalities.


Mehr über Db2 Audit

Presentation Outline

  • Audit needs and musts Take a journey to GLB HIPAA PCI‐DSS Basel III Sarbanes‐Oxley CA SB1386 Federal Information Security Management Act “ed Flag”Rules (FRCA)5.
  • Solution overview and their Pros/Cons Get an overview about the existing solutions and understand how they work.
  • The viable way – let Db2 do the magic! Learn about Db2 enhancements in Db2 10/11 that deliver the Db2 workload being processed and understand why it’s so efficient.
  • Customer results from the banking industry Receive some experience from a large banking company and how they successfully replaced their Db2 Audit feature based reporting by a modern SQL tracking and analytics process.


2Db2 12 Continuous Delivery – New challenges for deployment.

Fundamental changes in the Db2 z world often lead to concerns. Let’s face it – some changes force us to change! While a Db2 version migration usually took months, or even years, there will be no new Db2 version after 12, but continuous code drops.

This will have a tremendous impact on migration strategies, because we have to find a reliable way to test these code deliveries in a fraction of time. If we make it, Business Divisions will become enthused at how quickly new technology becomes available for new applications. This presentation will describe the difference between Code, Catalog, Function and Application Levels, how you can control them and how you can fallback in case of anomalies. It also illustrates how we still can be pro-active in testing without burning weeks and months.
Learn how to choose from four different levels of testing and a new way of automation. CD-Screening allows you to pick and choose from KPI based test automation. The levels include simple anomaly alerting, access path verification, clone Pre-apply and even workload capture/replay to easily discover different behaviour resulting from a new code Level.


Mehr über Db2 Continuous Delivery – CD

Presentation Outline

Joining this presentation, you’ll learn how to align Continuous Delivery to your Continuous Availability.

  • Agile, Continuous Delivery, DevOps – just buzz words, or new methodologies?
  • Db2 Code, Catalog, Function and Application Levels – differences and dependencies.
  • Activation/Deactivation of new code and how to fallback and when you can’t.
  • Different flavors of (pro-active) CD-Screening and how it can be automated:

* Anomaly alerting based on Incompatibility Change Indicators (ICIs)
* Dyn./Stat.Access Path Change Detection e.g.via Plan Management
* Clone based code change pre-apply exploiting Backup System
* Workload-KPI verification using SQL replay and KPI comparison

Audience Experience:   Intermediate Advanced
Platform:                        Db2 z/OS
Presentation Length:     60 minutes
Presentation Category:  Database Administration Performance Management Db2 Migration


3Db2 z/OS Lies, Damn lies, and Statistics…

– Benjamin Disraeli, Prime Minister of England (1868, 1874-1880)

The above line may, or may not, have been spoken well over 100 years ago, but the need for statistics and, above all else, accurate statistics is more important than ever in the Db2 world of today.


Mehr über Db2 RUNSTATS

Presentation Outline

  • Db2 RUNSTATS basics & catalog tables and Columns used for access path
  • IBM recommendations through the ages : from Db2 V3 to Db2 12
  • Db2 RUNSTATS advanced
  • SYSCOLDIST explained
  • RUNSTATS real world Q&A :
    use of SAMPLE, COLGROUP, PROFILE, REOPT (ONCE), TABLESAMPLE SYSTEM, HISTOGRAM, …
  • RUNSTATS reversal

Speaker biography

Roy Boxwell has more than 32 years of experience in MVS, OS/390, and z/OS environments – 30 of those in Db2. He specializes in installation, migration, and performance monitoring and tuning. Roy leads the SEG development team responsible for the real time database maintenance solutions. He is also an active participant, speaker and contributor on the IDUG Db2 Listserv and sends out a monthly Db2 z/OS Newsletter.

2017-11 Db2 APAR list: An APAR a day keeps the bugs at bay

Db2 12 APAR – time saving list

With all the talk about “agile” going on, and referring to one of my older 2017-09 newsletters* on APARs, I think it is time to tell you all about another little service that our company offers.

(completely free, simple and no marketing spam)


* Db2 12 Agile & APAR previous newsletter:
2017-09: Db2 12 SQL Access path: Death by APAR :  How many APARs really can affect access paths?

APAR Database

The APAR database can be accessed by anyone with an IBM Userid and you can merrily search to see if the problem that you have hit is already found and fixed, or a fix is in the works.

The problem is: What about the bugs that you do not *know* you have hit?

Get someone else to do the donkey work

The answer is to get someone else to do all the research for you, and deliver the answer by e-mail every month for all current releases of Db2 going back two years.

Who is that donkey? You will never guess…  😉

Three is the key

There are three Excel spread sheets here.


  1. SQL Performance
    The first is RTS. This lists any and all APARs to do with the Real-Time Statistics tables. If you rely on these tables to decide when to run REORG, COPY and RUNSTATS, then you want to make sure that they are being correctly updated, don’t you?


  2. SQL Access Path
    The second is RUNSTATS. RUNSTATS is a critical utility program and contains bugs like any other non-trivial program. I count RUNSTATS bugs as *always* a personal HIPER. I rely on statistics and so does the Db2 Optimizer. If there is bad data here, then your access paths have no chance!


  3. Performance PTFs
    Finally, and the biggest list, is those APARs that have anything to do with SQL Performance and SQL Access paths (If not already in the RUNSTATS list of course!) Performance PTFs are pretty important!

Going hyper over HIPER

All the APARs have their related PTF. A handy little HIPER column tells you whether or not this is a really important fix. As I mentioned, I treat the RUNSTATS ones as personal HIPERS. Also added is a PE indicator when a PTF goes bad on you (PTF in Error) so you can see if you introduced a problem by correcting another.

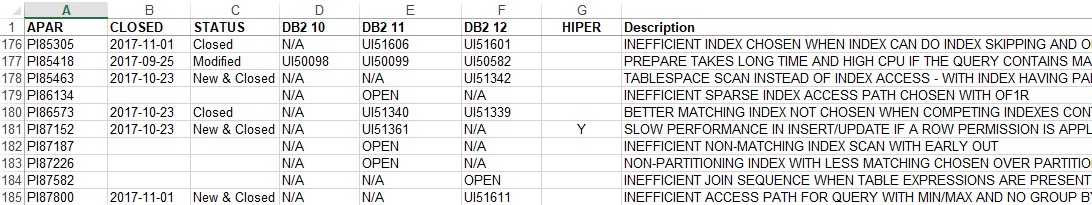
One Excel Example: The SQL Performance spread sheet

Db2 12 APAR list free for Db2 z/OS: SQL Performance (RTS) - Performance PTFs - SQL Access Path (RUNSTATS) -

This is from the SQL Performance spread sheet and you can see how it looks.

The same table in HTML:

APARCLOSEDSTATUSDb2 10 Db2 11Db2 12HYPERDescription
PI85305
2017-11-01
Closed
N/A
UI51606
UI51601
INEFFICIENT INDEX CHOSEN WHEN INDEX CAN DO INDEX SKIPPING…
 PI85418
 2017-19-25
Modified
UI50098
UI50099
UI50582
PREPARE TAKES LONG TIME AND HIGH CPU IF THE QUERY CONTAINS MA…
 PI85463
New & Closed
 N/A
 N/A
UI51342
TABLESPACE SCAN INSTEAD OF INDEX ACCESS – WITH INDEX HAVIN…

 …

 …

 …

 …

 …

 …

 …

 …

Interested in making your life a little bit easier and safer?

If you are interested in Db2 APARs and you have *no* time to go and scrabble around the internet trying to find out which APARs are needed, worthwhile, or dangerous, then

just email our technical support techsupport@seg.de and ask to be added to the APAR Mailing list.

It is completely free, you will not get marketing spam and it really is as simple as that!


Get AGILE now!

With these handy lists, you can quickly and easily review the state of your Db2, and react quickly and in a timely manner when you have to.


As usual, if you have any comments or queries please feel free to drop me a line!

TTFN


Roy Boxwell

Michigan Db2 Users Group – Dezember 2017

MDUG – Michigan Db2 Users Group

06. Dezember 2017

SEGUS & SOFTWARE ENGINEERING präsentieren

1- 25 Years of Missed Opportunities? SQL Tuning Revisited

2- Db2 z/OS Lies, Damn Lies, and Statistics


1- 25 Years of Missed Opportunities? SQL Tuning Revisited

“But that’s the way we’ve always done SQL Tuning” – sound familiar?

The definition of madness is to keep doing the same thing and expecting a different outcome.
Find out how to stop the madness.

Nothing is more expensive than a missed opportunity” (H. Jackson Brown, Jr).

This is especially true when it comes to SQL Tuning!

There are many low-hanging fruits within easy grasp of anyone tasked with tuning their systems. But how do you know what is dangling within reach if you can’t see it?

Find out how a modern DB2 z/OS SQL warehouse can collect and store all executed static and dynamic SQL (plex-wide) with basically no overhead.

By comparing SQL statements side-by-side, the “easy pickings” will immediately become apparent. But why stop there? Experts can effortlessly dig deeper and find the totally hidden gems: Disc Problem Detection, Delay Detection, Never executed SQL, SQL Timeline. Precisely pinpoint specific areas to target and get the most out of your DB2 system – while reducing costs.

Outlines

1 – Tuning SQL – how we always done it

2 – Single SQL, package, application

3 – Tuning SQL – year 2004 – ACCESS PATH comparison and simulation

4 – Tuning SQL Revisited – A new methodology

5 – Harvesting the low hanging fruit


2- Db2 z/OS Lies, Damn Lies, and Statistics

..Lies, damn lies, and statistics… – Benjamin Disraeli, Prime Minister of England (1868, 1874-1880)

The above line may, or may not, have been spoken well over 100 years ago, but the need for statistics and, above all else, accurate statistics is more important than ever in the Db2 world of today.

Presentation Outline

  • Db2 RUNSTATS basics & catalog tables and Columns used for access path
  • IBM recommendations through the ages : from Db2 V3 to Db2 12
  • Db2 RUNSTATS advanced
  • SYSCOLDIST explained
  • RUNSTATS real world Q&A :
    use of SAMPLE, COLGROUP, PROFILE, REOPT (ONCE), TABLESAMPLE SYSTEM, HISTOGRAM, …
  • RUNSTATS reversal

Speaker Biography

Ulf Heinrich is the Director of Solutions Delivery at SOFTWARE ENGINEERING GmbH. He specializes in Db2 recovery issues and database maintenance, focusing on the growing requirement for cost reduction and 24×7 operations. As a consultant at large customer sites, he has implemented database maintenance procedures and recovery strategies, and also experienced the pitfalls of recovery scenarios under real‐world recovery pressure. His activities cover EMEA, as well as North America through SE’ U.S. subsidiary, SEGUS Inc. He’s involved in the development of SE’ maintenance and recovery Solutions.

Northeast Ohio Database Users Group – Dezember 2017

NEODBUG – Northeast Ohio Database Users Group – Dezember 2017

07. Dezember 2017

SEGUS & SOFTWARE ENGINEERING präsentieren

1- 25 Years of Missed Opportunities? SQL Tuning Revisited

2- Db2 z/OS Lies, Damn lies, and Statistics


1- 25 Years of Missed Opportunities? SQL Tuning Revisited

“But that’s the way we’ve always done SQL Tuning” – sound familiar?

The definition of madness is to keep doing the same thing and expecting a different outcome.
Find out how to stop the madness.

Nothing is more expensive than a missed opportunity” (H. Jackson Brown, Jr).

This is especially true when it comes to SQL Tuning!

There are many low-hanging fruits within easy grasp of anyone tasked with tuning their systems. But how do you know what is dangling within reach if you can’t see it?

Find out how a modern DB2 z/OS SQL warehouse can collect and store all executed static and dynamic SQL (plex-wide) with basically no overhead.

By comparing SQL statements side-by-side, the “easy pickings” will immediately become apparent. But why stop there? Experts can effortlessly dig deeper and find the totally hidden gems: Disc Problem Detection, Delay Detection, Never executed SQL, SQL Timeline. Precisely pinpoint specific areas to target and get the most out of your DB2 system – while reducing costs.

Outlines

1 – Tuning SQL – how we always done it

2 – Single SQL, package, application

3 – Tuning SQL – year 2004 – ACCESS PATH comparison and simulation

4 – Tuning SQL Revisited – A new methodology

5 – Harvesting the low hanging fruit


2- Db2 z/OS Lies, Damn lies, and Statistics

..Lies, damn lies, and statistics… – Benjamin Disraeli, Prime Minister of England (1868, 1874-1880)

The above line may, or may not, have been spoken well over 100 years ago, but the need for statistics and, above all else, accurate statistics is more important than ever in the Db2 world of today.

Presentation Outline

  • Db2 RUNSTATS basics & catalog tables and Columns used for access path
  • IBM recommendations through the ages : from Db2 V3 to Db2 12
  • Db2 RUNSTATS advanced
  • SYSCOLDIST explained
  • RUNSTATS real world Q&A :
    use of SAMPLE, COLGROUP, PROFILE, REOPT (ONCE), TABLESAMPLE SYSTEM, HISTOGRAM, …
  • RUNSTATS reversal

Speaker Biography

Ulf Heinrich is the Director of Solutions Delivery at SOFTWARE ENGINEERING GmbH. He specializes in Db2 recovery issues and database maintenance, focusing on the growing requirement for cost reduction and 24×7 operations. As a consultant at large customer sites, he has implemented database maintenance procedures and recovery strategies, and also experienced the pitfalls of recovery scenarios under real‐world recovery pressure. His activities cover EMEA, as well as North America through SE’ U.S. subsidiary, SEGUS Inc. He’s involved in the development of SE’ maintenance and recovery Solutions.